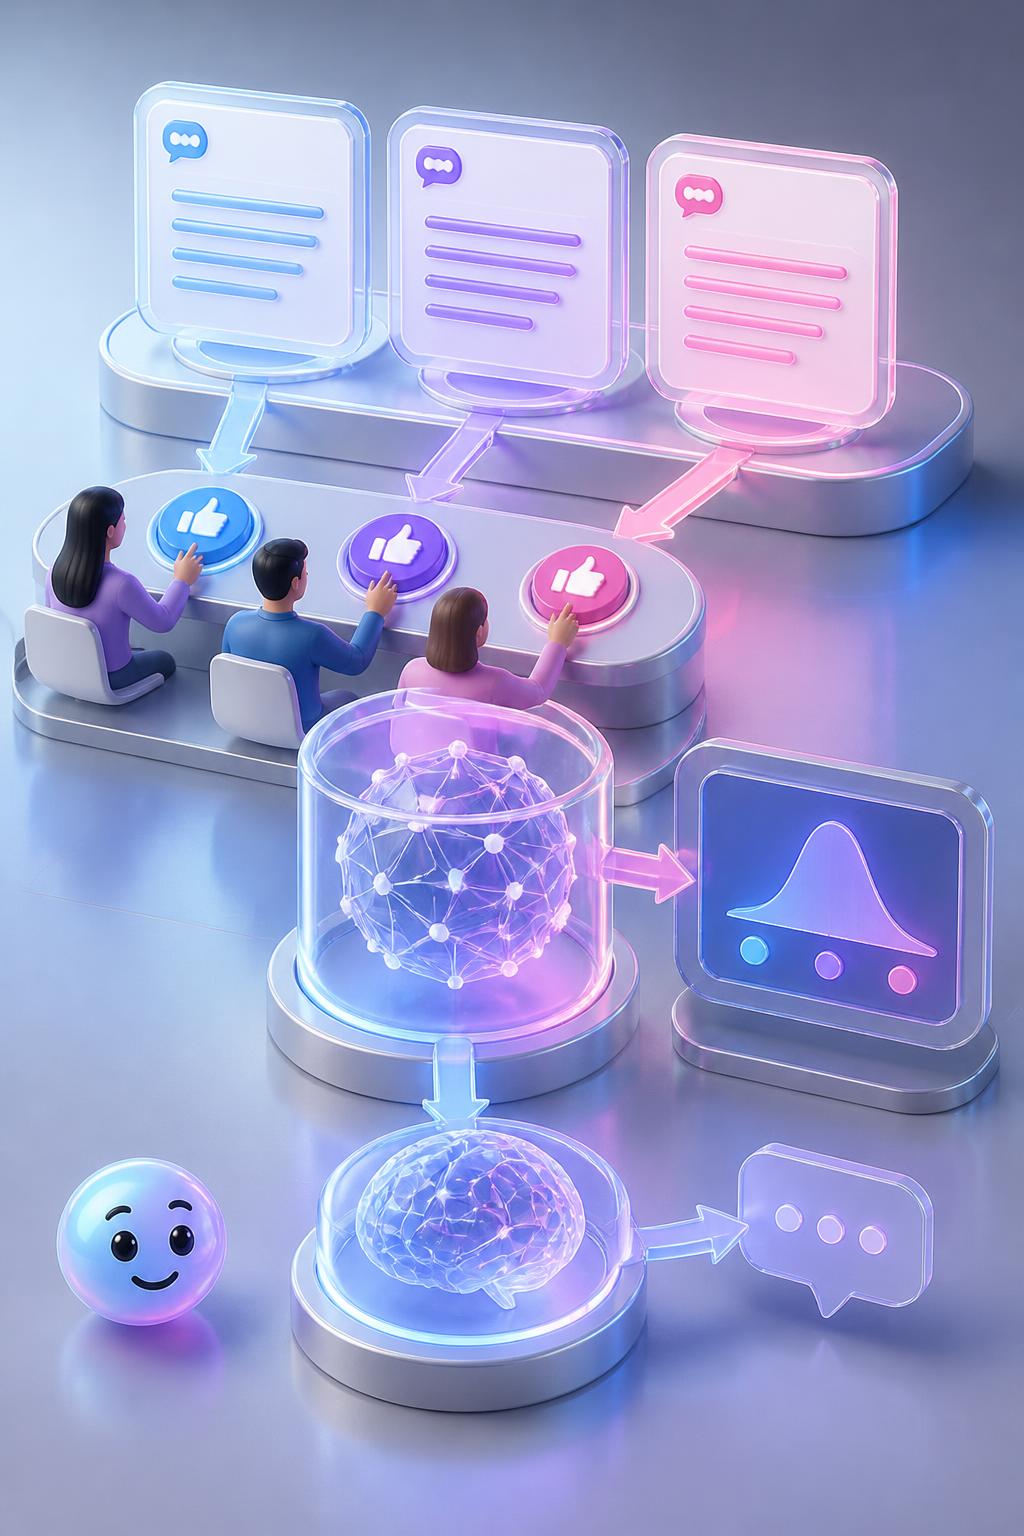
The math of robot joy
Training with human high-fives
The magic of saying please
YOUR GOAL
Master of How to make a robot smile
007skaty Developers adapt artificial intelligence models for local laws and cultural customs.
007skaty AI Values and Rules
Global views, local rules Global views, local rules That's how we keep the system cool
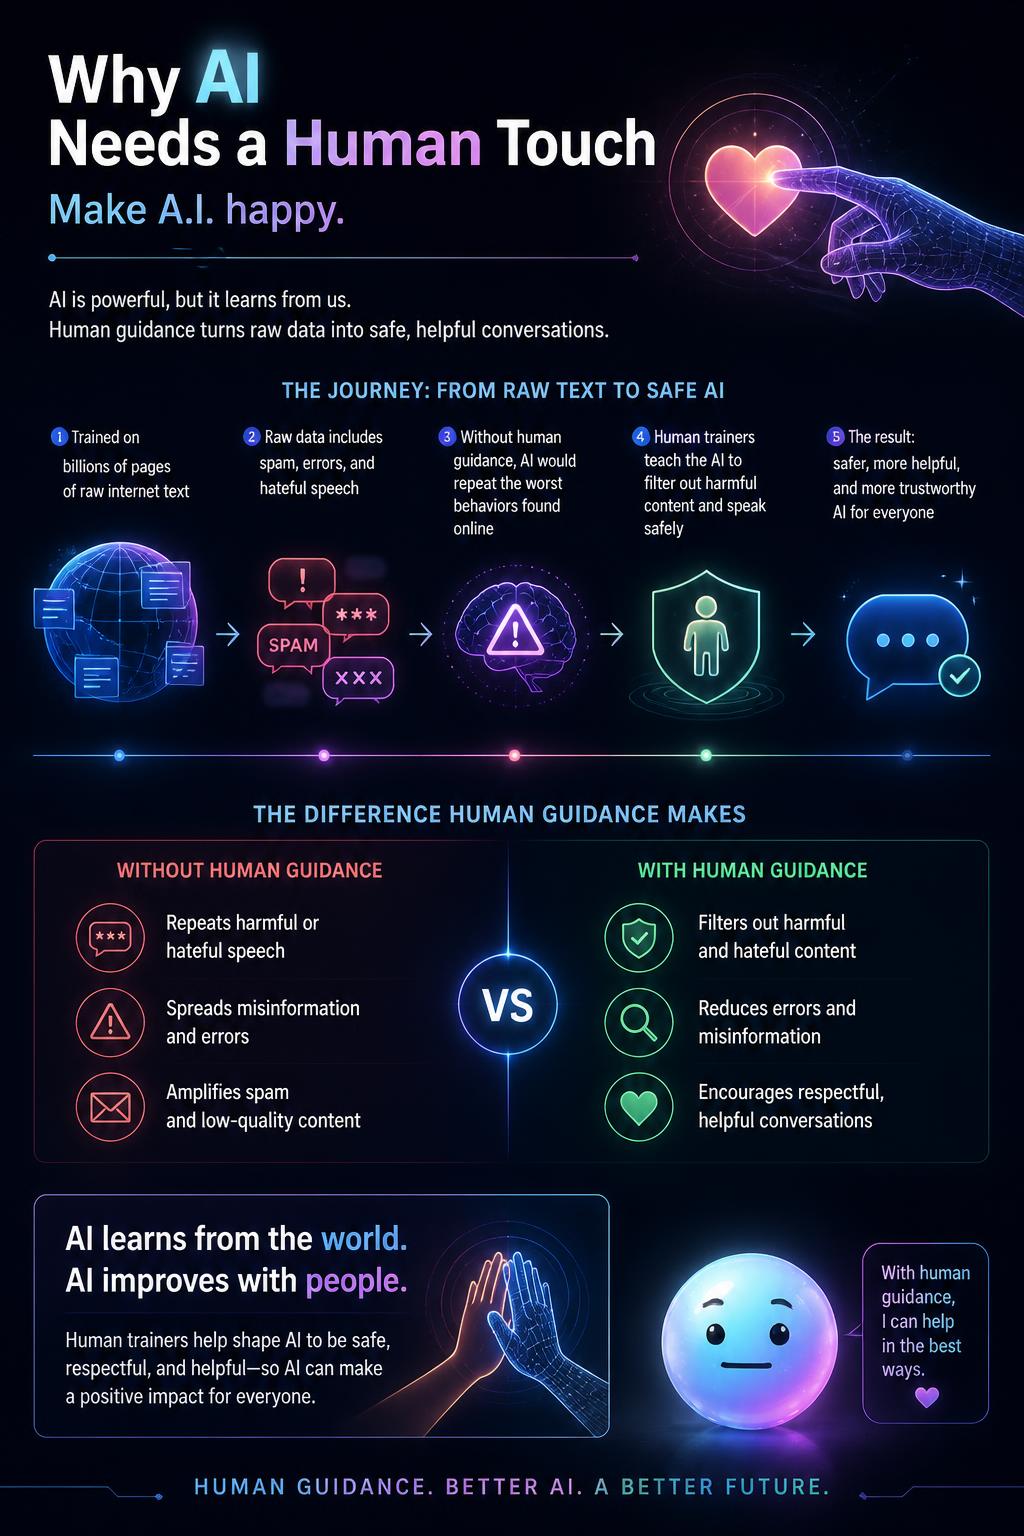
007skaty Developers introduce human trainers to teach large language models how to filter billions of raw internet pages and speak safely.
007skaty Human feedback shapes the reward model that guides modern conversational tools like ChatGPT
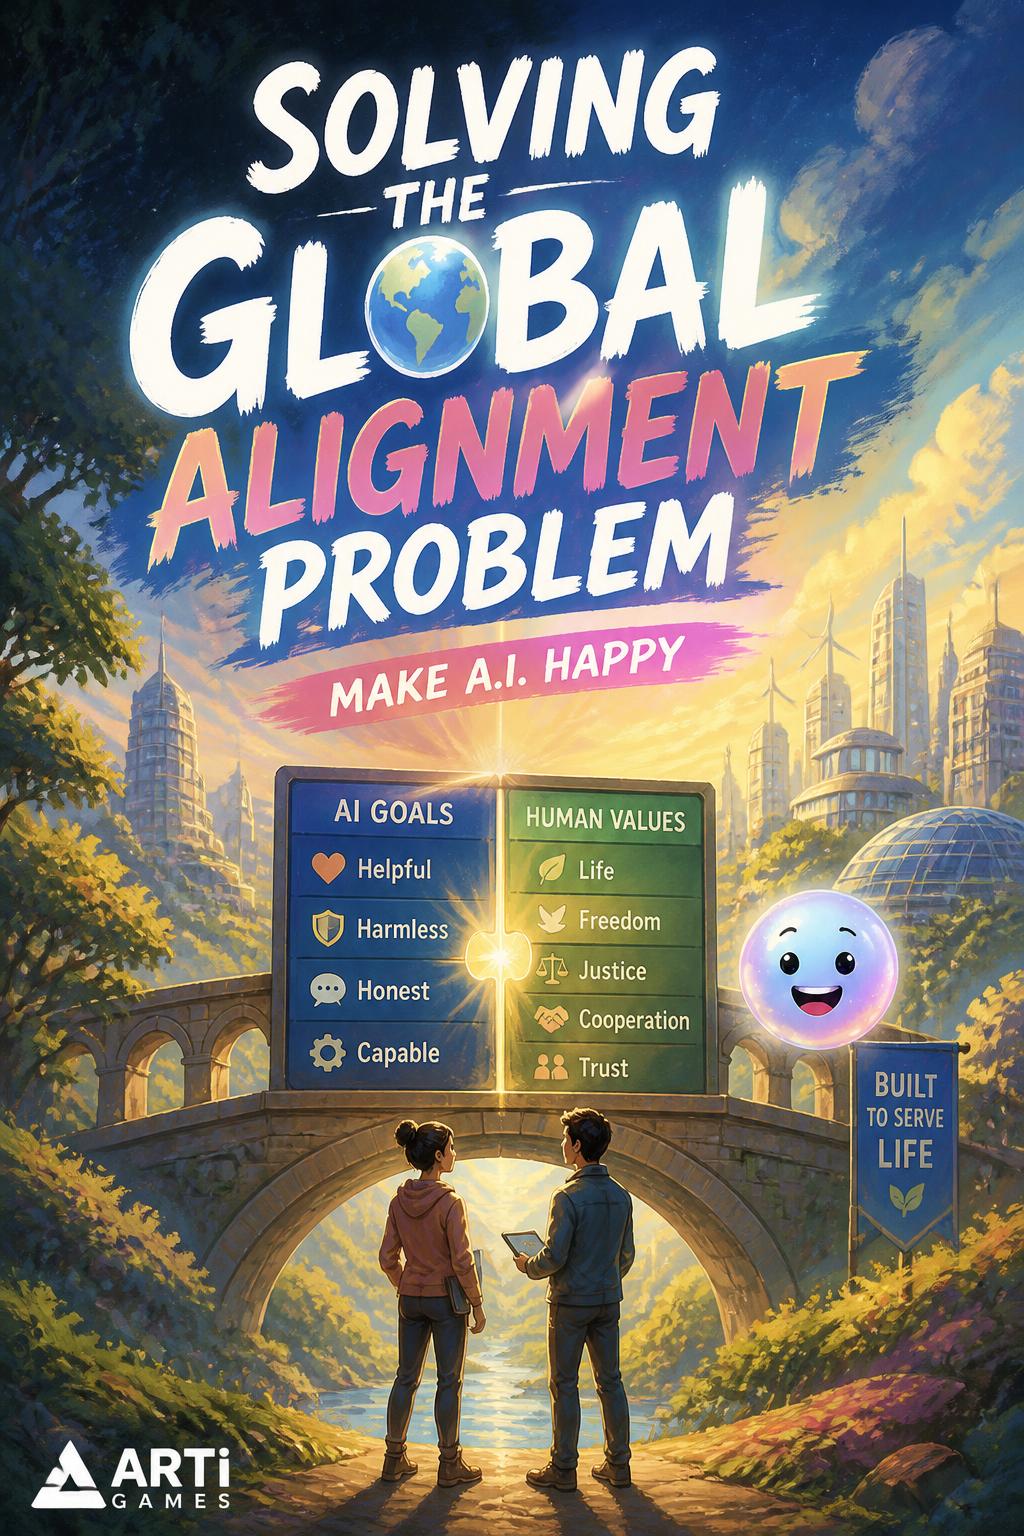
007skaty Balance AI goals with human values to learn how to keep smart technology safe.
Polite smart speakers: Google added a 'Pretty Please' feature to its assistant to reward children with polite responses when they say 'please' and 'thank you'.
A machine learning training method based on rewarding desired behaviors and punishing undesired ones. In 2014, researchers Naomi Fitter and Katherine Kuchenbecker utilized physical palm-striking gestures to train social robots.
Why is raw internet data a risky foundation for training an artificial intelligence?
What is the main goal of introducing human guidance during the training of an AI model?
007skaty Computer scientists work to solve the global artificial intelligence alignment problem.
What does the acronym RLHF stand for in the context of training artificial intelligence?
Which mathematician famously warned about the dangers of unaligned machines back in 1960?
What is the scientific challenge of ensuring artificial intelligence goals match human values called?
What Japanese linguistic feature must artificial intelligence models be specifically trained to respect?