Chapter 1
The giant digital vacuum cleaner
Chapter 2
The mysterious black box
Chapter 3
When robots make things up
Chapter 4
The battle for the internet's words
Ch 1 · The giant digital vacuum cleaner
007skaty BookCorpus AI Training
Indie romance, hidden in the code, teaching machines how to speak.
BETA
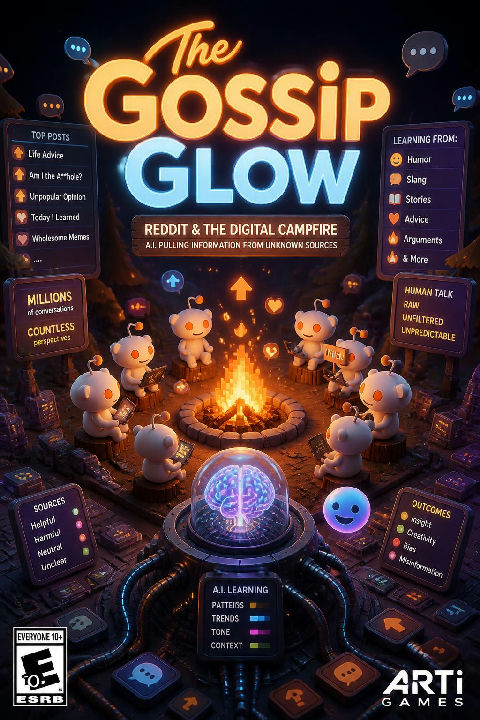
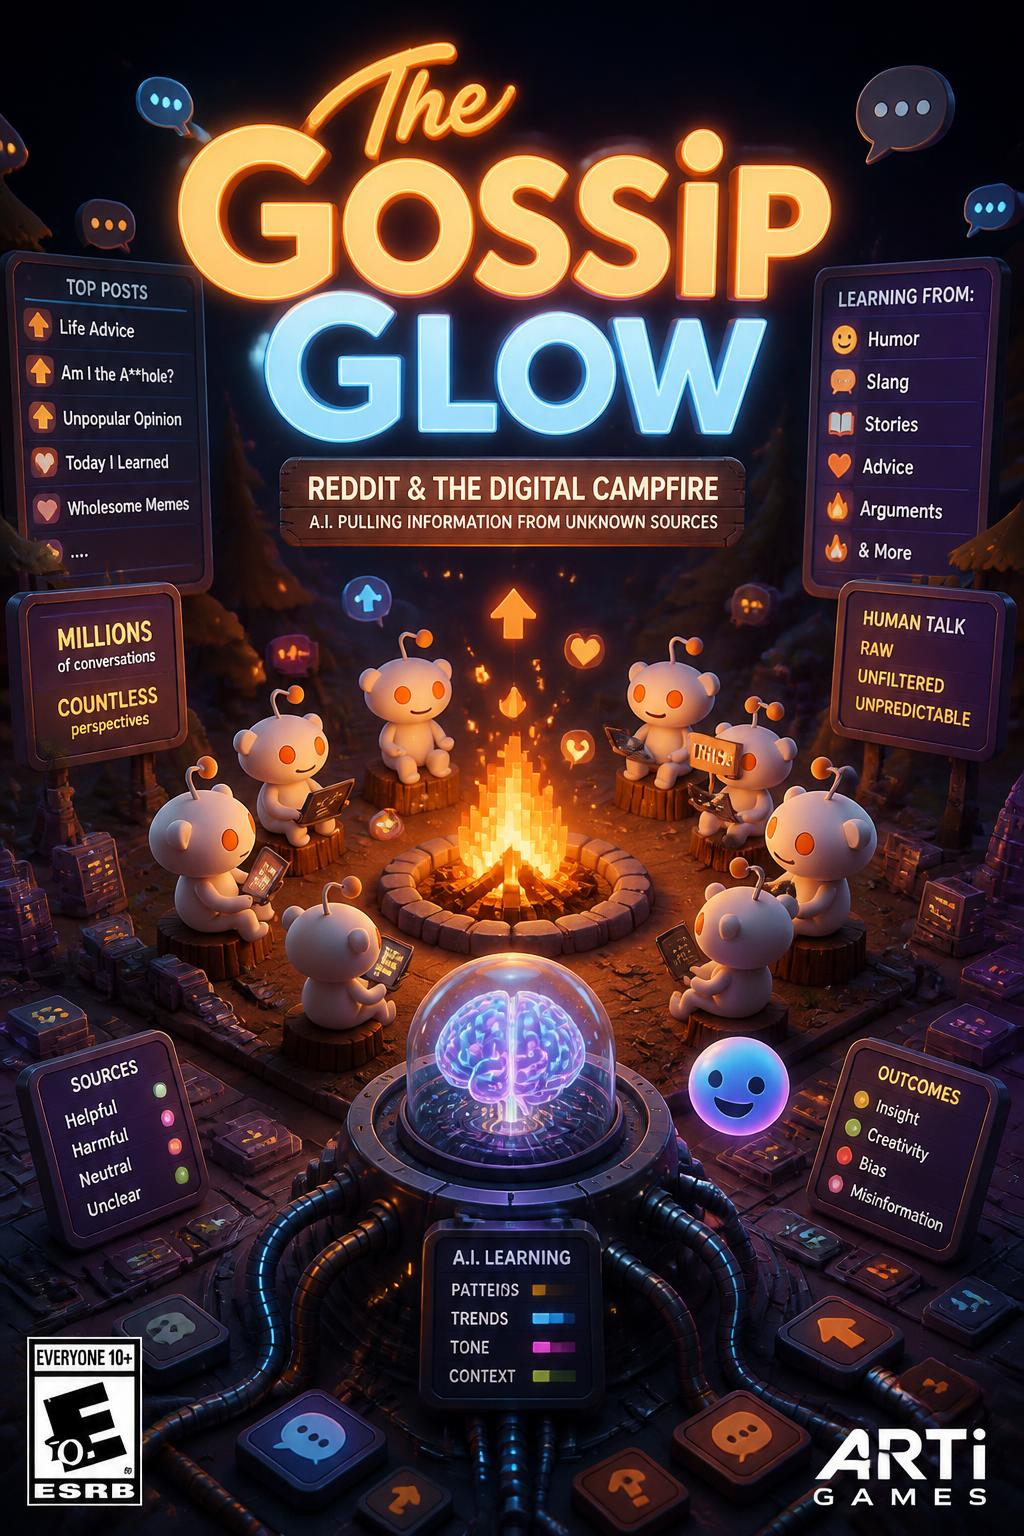
007skaty Trace the glowing rumors to learn how AI pulls information from unknown sources.
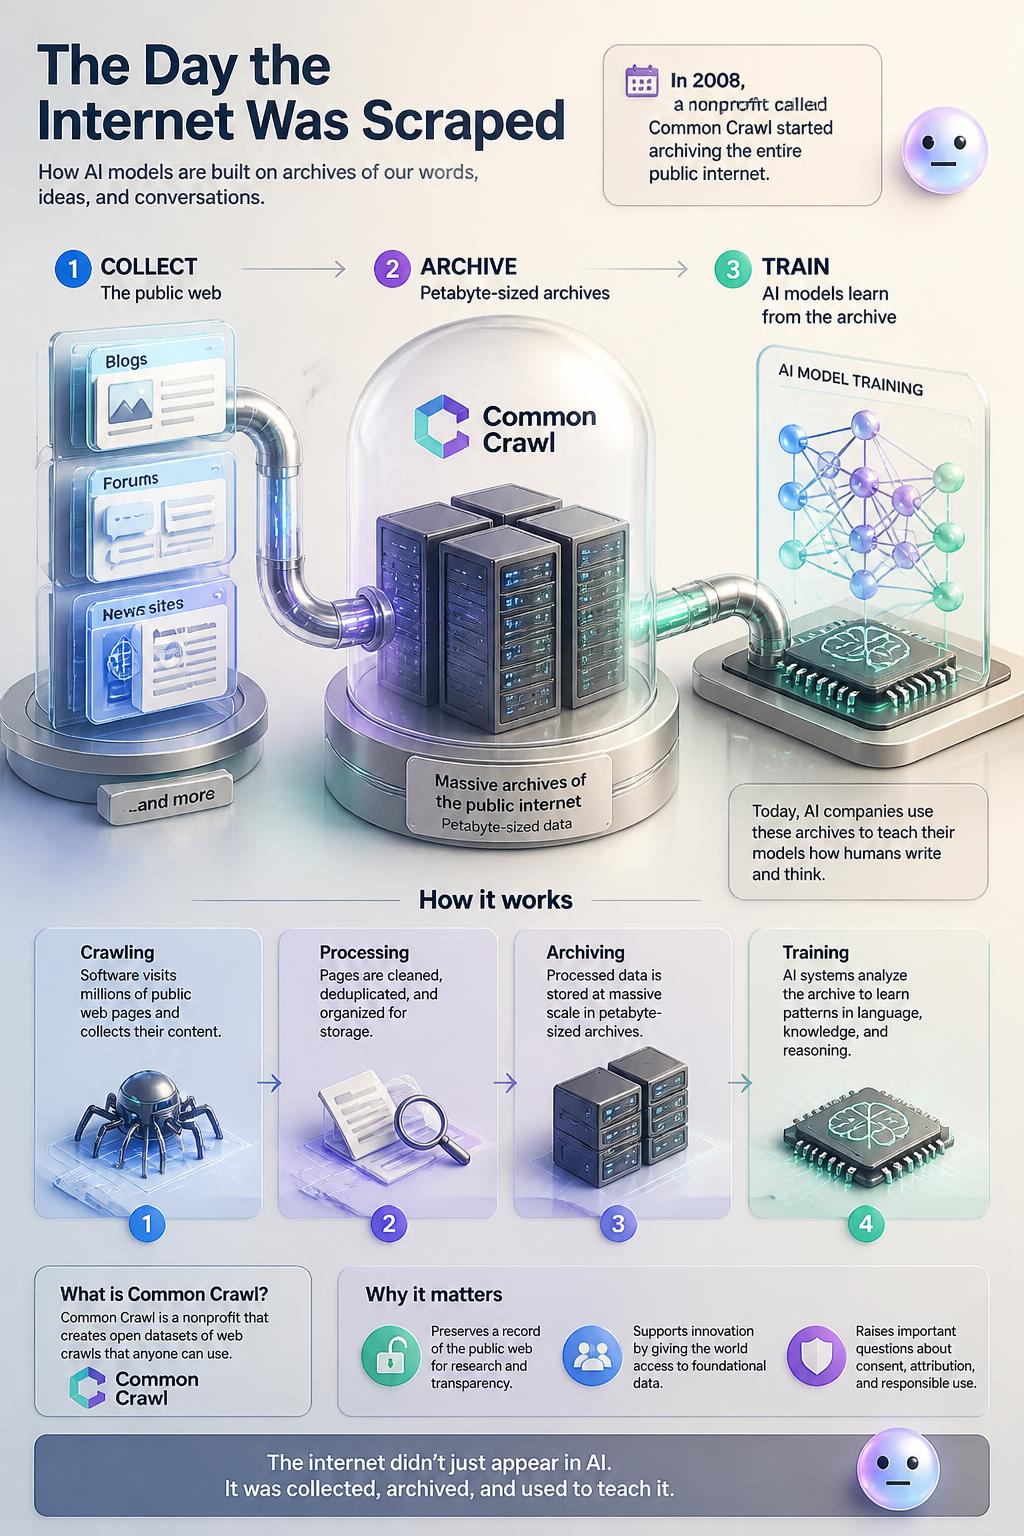
007skaty Since 2008, this project has saved petabytes of public blogs, forums, and news to teach AI how humans write and think.
Quiz
What is the primary purpose of the nonprofit organization Common Crawl, founded in 2008?
Quiz
Approximately how much data does a petabyte represent, often used to measure massive AI training datasets?
007skaty Private datasets prevent researchers from finding bias and errors in new AI models.
Quiz
Why do modern artificial intelligence companies keep their newer training datasets secret?
Quiz
Which major open-source dataset, containing billions of image-text pairs, was widely used to train early image-generating AIs?
Fun Fact
AI library size: If you printed out the text used to train a modern AI, the stack of paper would reach all the way into space!
Quiz
What is a major risk when AI models are trained on raw, unfiltered social media conversations?
Quiz
In 2016, which Microsoft chatbot was shut down within 24 hours of launch after Twitter users taught it to tweet offensive statements?
Glossary
web scraping (noun)
The automated process of extracting data from websites. In 2020, OpenAI compiled massive datasets of scraped online text to train its GPT-3 language model.
The automated process of extracting data from websites. In 2020, OpenAI compiled massive datasets of scraped online text to train its GPT-3 language model.
Quiz
Why is high-quality book text preferred over standard social media posts for training artificial intelligence?
Quiz
What was the controversial dataset 'Books3' that was widely used to train machine learning models?