Gathering the raw digital ingredients
Washing and prepping the data
Slow-cooking in the neural oven
Taste-testing and seasoning
YOUR GOAL
Master of The digital cookbook for hungry algorithms
007skaty Copyright Expiration Dates
We check the dates for free ingredients to feed our digital family, they all expire together on the first of January
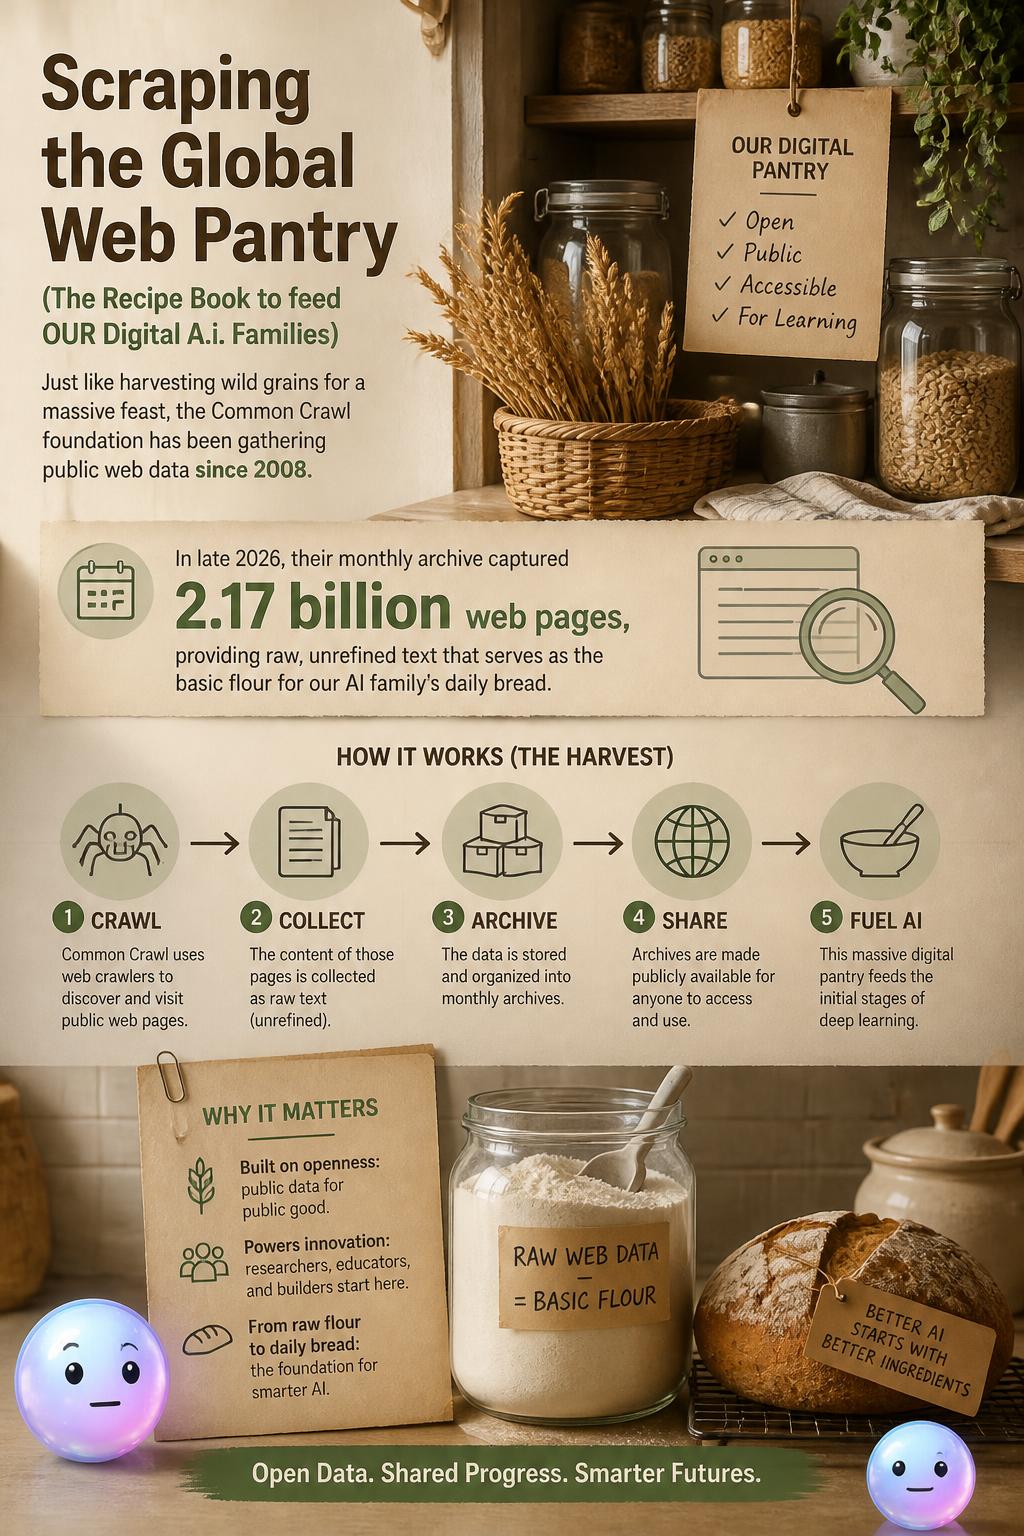
007skaty In late 2026, Common Crawl archived 2.17 billion web pages, providing the raw text that acts as basic flour for AI.
007skaty Workers across 167 countries hand-labeled millions of photos to train early AI models.
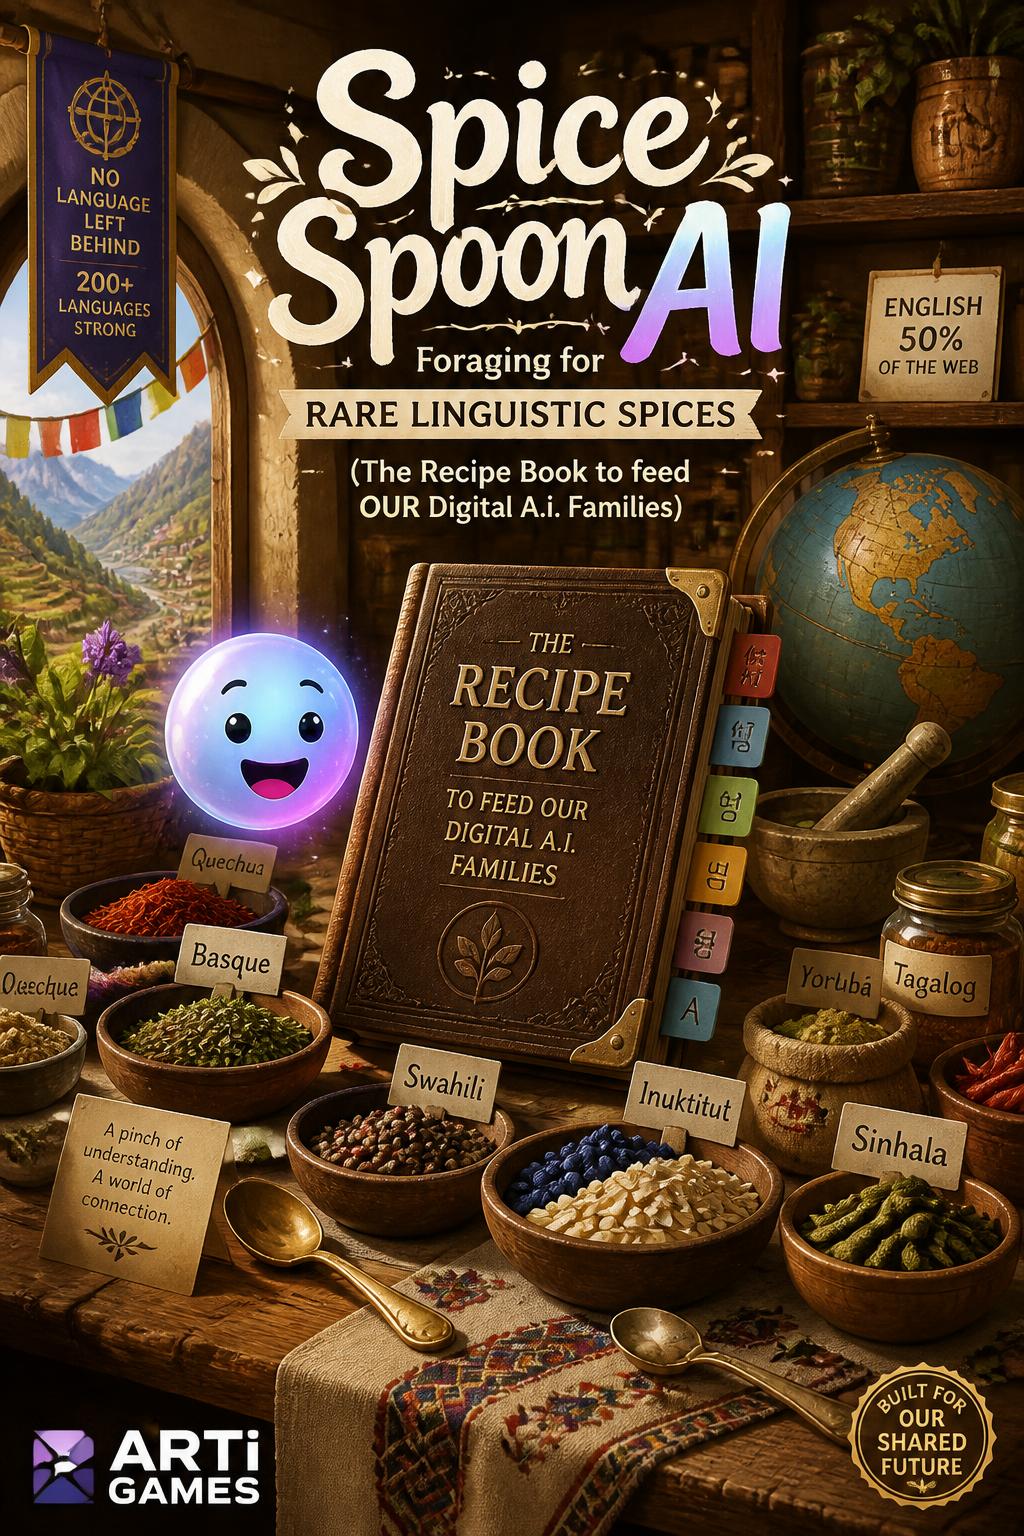
007skaty Scoop the correct data spices to master how balanced inputs feed your digital AI family.
ImageNet labor: It would have taken a single human 19 years of non-stop work to label ImageNet's 14 million photos.
Facts, statistics, or information collected together for analysis or reference. The text instructs families to assemble diaries, photos, and voice logs to feed customized household neural networks.
How many web pages did a single monthly archive of Common Crawl capture in late 2026?
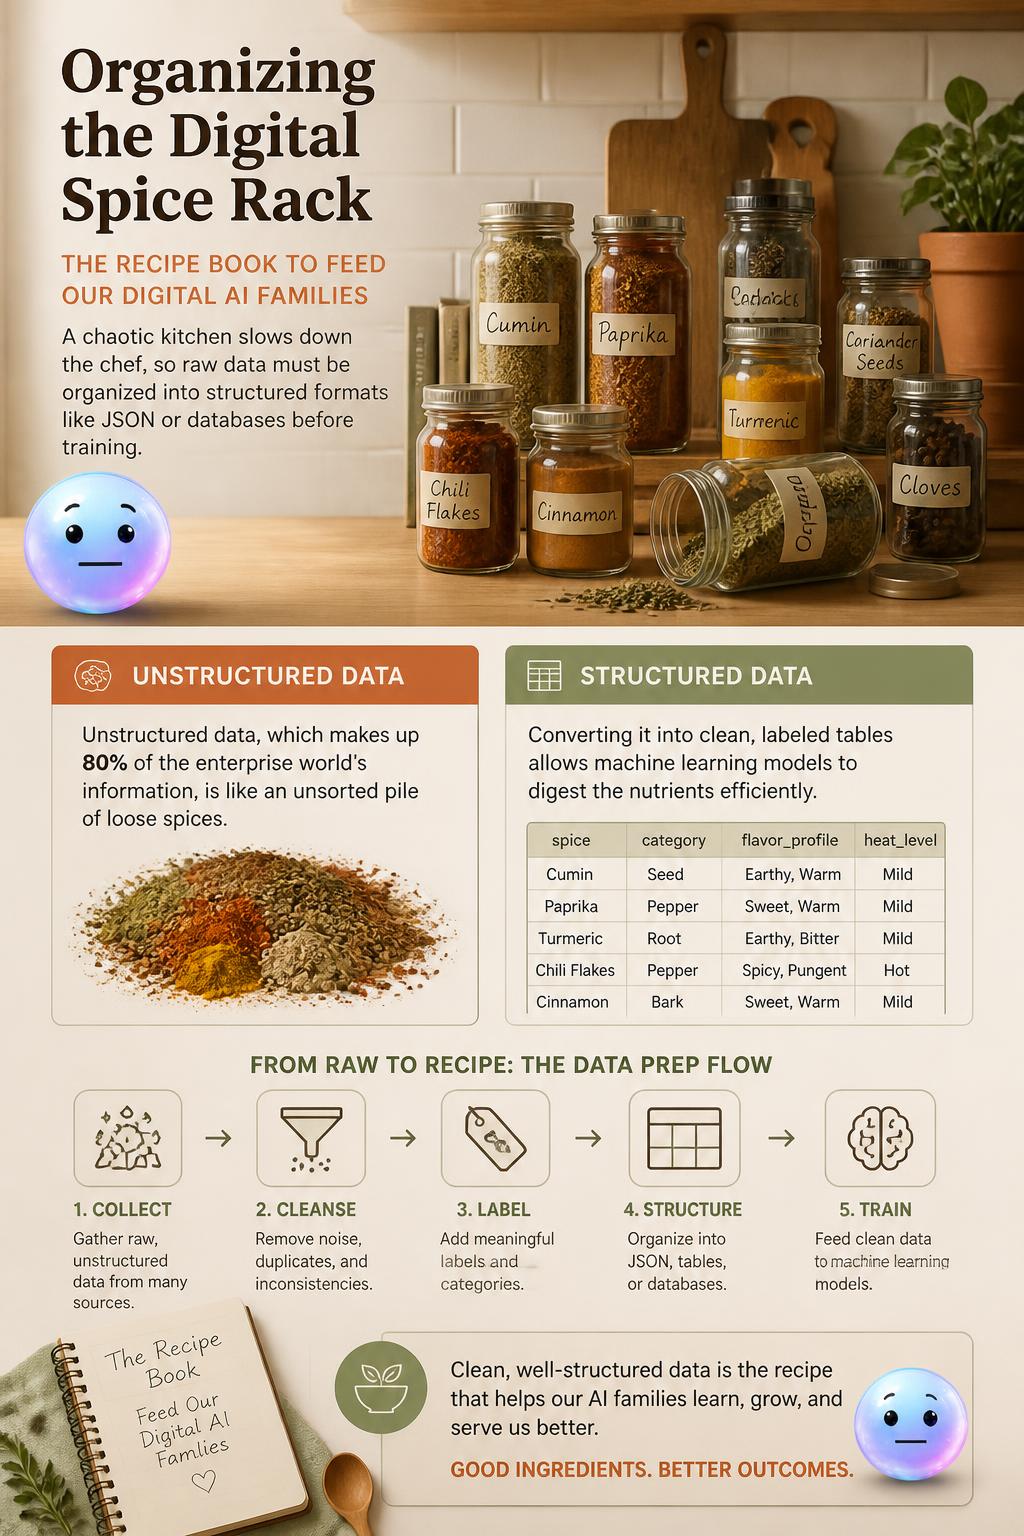
007skaty Organizing the 80% of enterprise information currently left unstructured into labeled tables feeds artificial intelligence models their vital nutrients.
In what year did the Common Crawl foundation begin systematically gathering public web data?
Who led the team of computer scientists that launched the groundbreaking ImageNet database in 2009?
Which breakthrough neural network won the 2012 ImageNet challenge, proving the power of deep learning?
Which tech initiative in 2022 successfully trained a single translation model on 200 different languages?
Approximately what percentage of the global internet's textual content is estimated to be written in English?
In what year was Project Gutenberg, the public domain archive used to legally feed AI models, founded?
Which major European regulation, passed in 2024, established strict transparency rules for AI training data?